Peer-reviewed, WACV 2025
Seeing Eye to AI: Comparing Human Gaze and Model Attention in Video Memorability
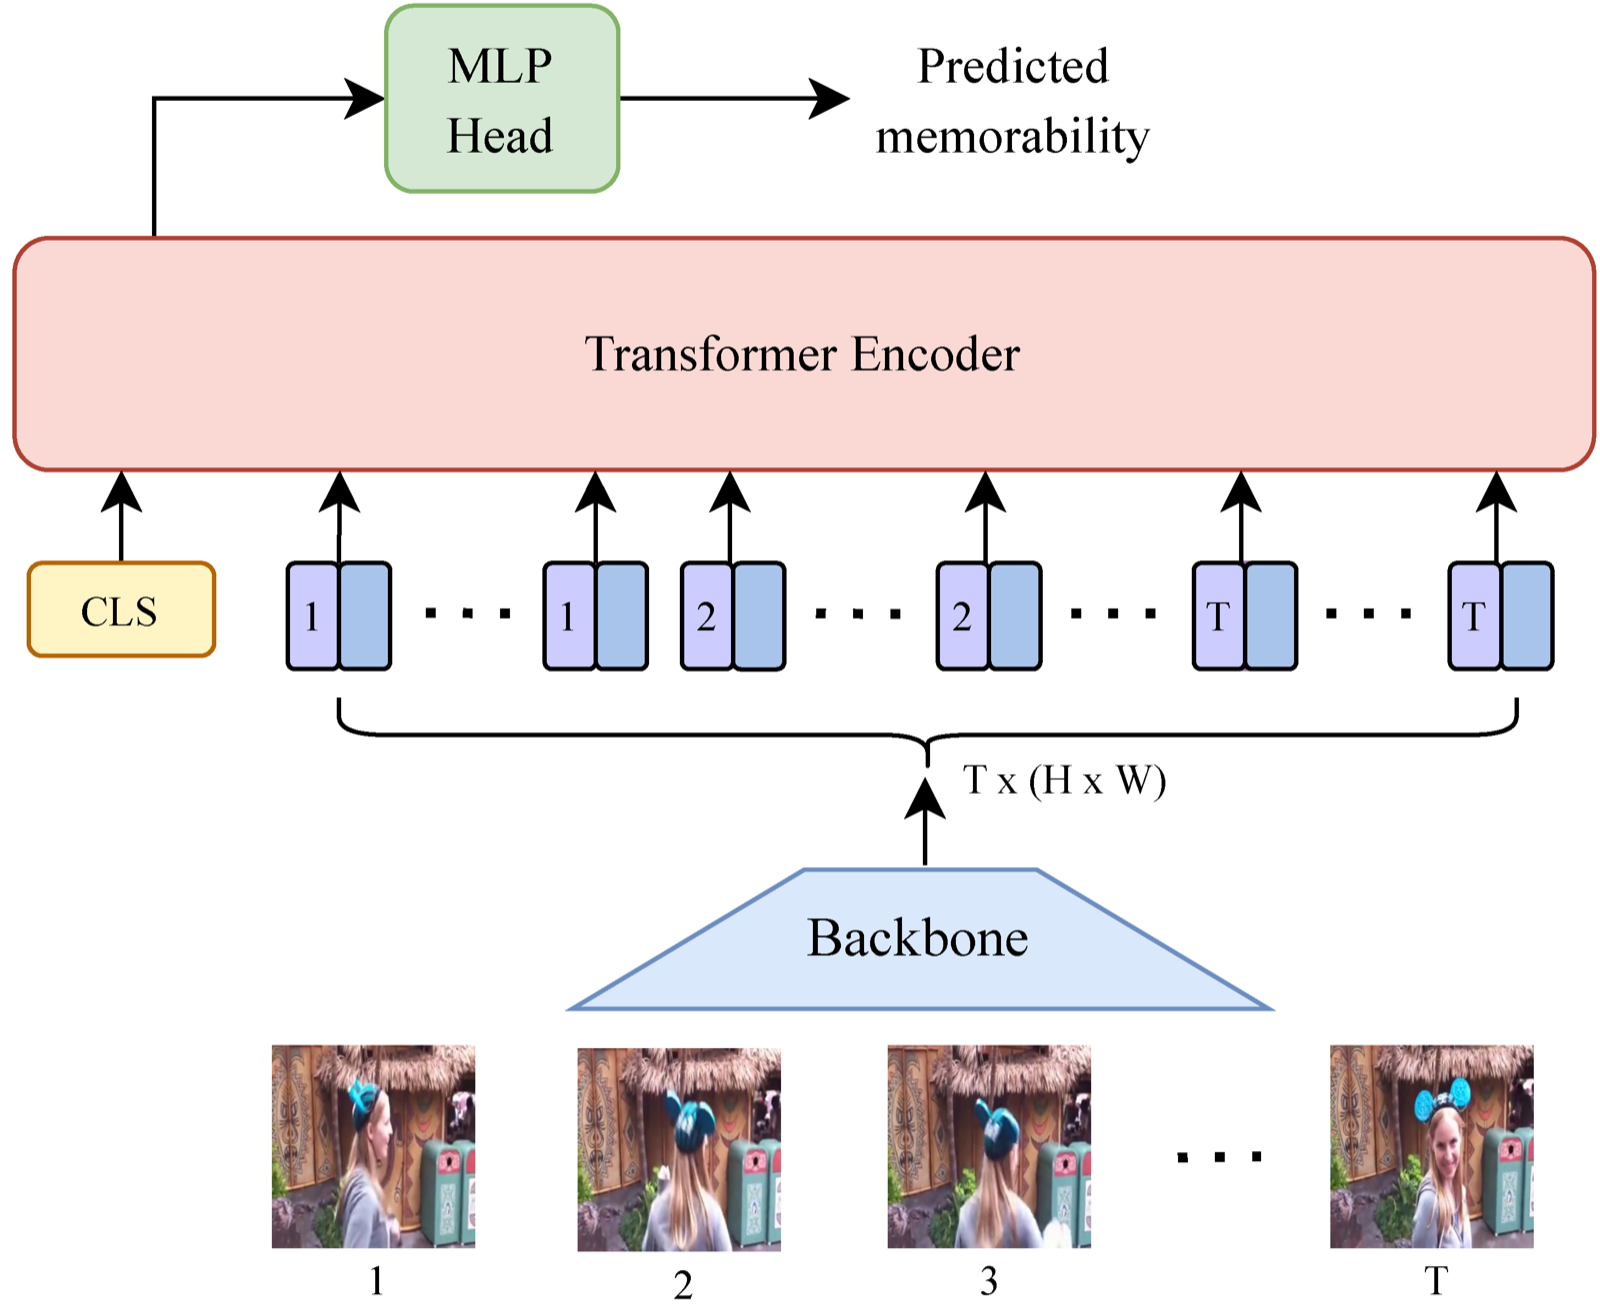
When a model is trained only to predict how memorable a video is, does it end up attending to the same things people look at? We built a CNN–Transformer memorability model whose attention can be read out over space and time, collected eye-tracking data from people doing a video memory task, and compared the two using saliency metrics, temporal analyses, and panoptic segmentation.